Your Data, Connected, Cleaned and Ready for AI.
Most AI projects stall on the data, not the AI. We scope and build the pipeline that pulls records from the systems you already run, fixes formats and duplicates, and delivers one clean, current dataset — the foundation every automation depends on. Delivered as a documented project, so it qualifies for grant support.
Scoped project · typically 4 to 8 weeks · eligible for EDGE Grant and IMDA support.
In a complimentary 60-minute consultation, you'll get:
- Which systems and spreadsheets hold the data you need
- What 'clean' has to mean for your first AI use case
- Where the data should live so every automation can use it
Data Work Is Where Grants Help Most
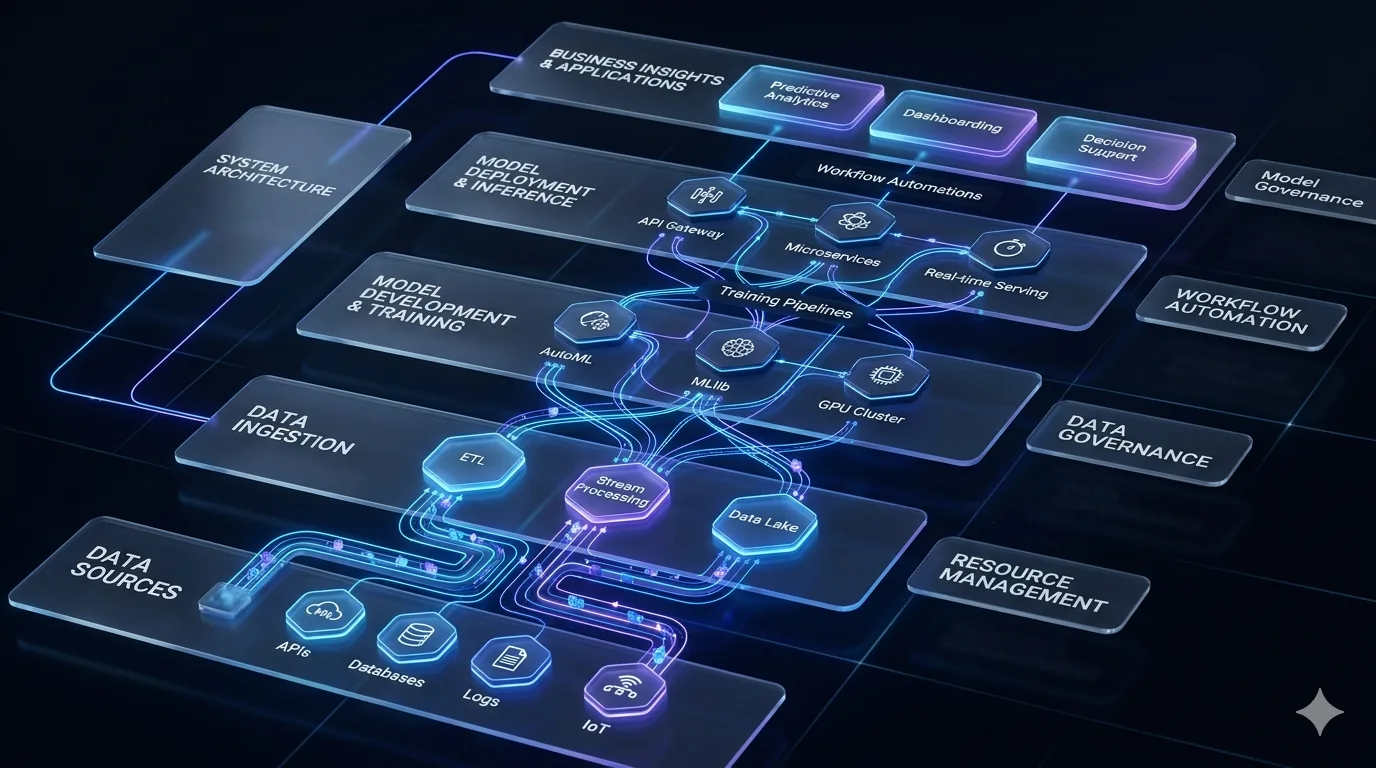
Grant schemes fund consultancy, scoping and documented delivery. That is exactly what a data engineering project is, which is why we run it as bespoke work rather than a fixed-scope pre-built automation.
Grant-eligible by design
Scoping report, data audit, architecture and hand-over documentation are part of the deliverable, which is what EDGE and IMDA assessors look for.
Sized to your systems
Two spreadsheets or six systems: the project is scoped to your sources, your definition of clean, and the automations that will use the data.
Feeds everything after it
The five pre-built automations and any custom agent run on the dataset this project delivers, so the value compounds.
Not sure whether you qualify or which scheme fits? We check it in the complimentary consultation. See the grants we work with
From Scattered Sources to One Reliable Dataset
Invoices in the accounting system, customers in the CRM, stock in a spreadsheet, bookings in a booking tool — every business runs on data spread across systems that were never designed to talk to each other. That is the single most common reason a ready-made AI automation cannot simply be switched on.
This is one pre-built automation with a fixed scope — it moves, cleans and organises the data, and leaves the business logic to the automations that sit on top of it:
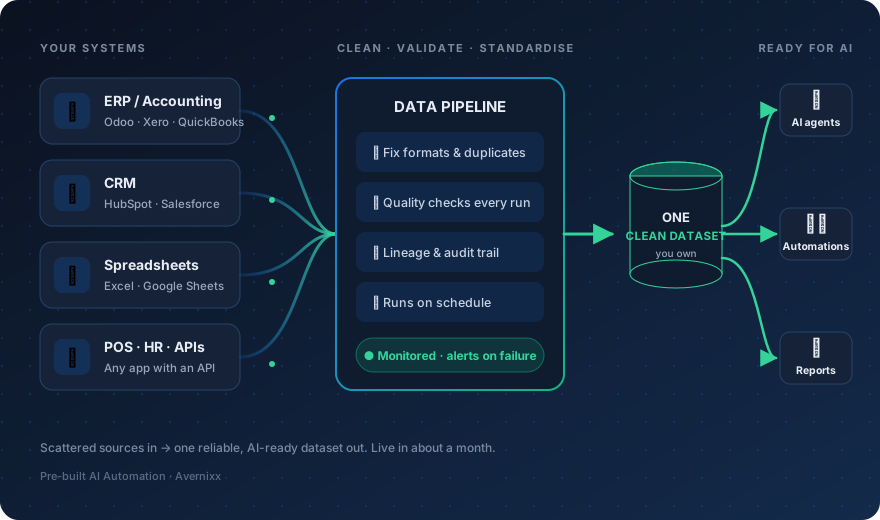
Pulls from ERP, CRM, accounting tools, POS, spreadsheets, databases and APIs — Odoo, Xero, HubSpot, Google Sheets and more.
Fixes dates, currencies, names and codes into one consistent format; removes duplicates and obvious errors.
Every run checks completeness and consistency, and flags anything that fails before it reaches your reports or AI.
Delivers the clean dataset to a database or warehouse you own, on a schedule — hourly, daily, or on demand.
Alerts when a source changes or a run fails, and records where every field came from for audit and troubleshooting.
What Data Engineering & AI Readiness Delivers
The payoff shows up in every report and every automation that runs on the data — usually within the first scheduled run.
Every team and every automation reads from the same clean, current dataset instead of five conflicting copies.
The exporting, copy-pasting and reformatting that used to eat the start of every week runs on its own.
Automated quality checks on every load — missing fields, broken formats and duplicates are caught before anyone acts on them.
You can trace any number in any report back to the system and record it came from — which auditors and grant assessors ask for.
Once the pipeline is running, every other pre-built automation becomes a much shorter project, because the data it needs is already clean and already flowing. This is the automation we most often recommend first.
A Scoped Project, Typically 4 to 8 Weeks
Scoping (Week 1)
Inventory your data sources, agree the target dataset, and define what 'clean' means for the first use case.
Connectors (Week 2)
Connect each source, set up the cleaning and standardisation rules, and choose where the data will live.
Validation (Week 3)
Run the full pipeline on real data, review the quality reports with your team, and tune the checks.
Go Live (Week 4)
Switch on the schedule and alerts, hand over the dashboard, and monitor the first week of runs.